If you’ve noticed AI models taking longer to answer certain questions lately, you’re not imagining things. A growing number of models now use what’s called inference time compute—essentially, they spend more processing power thinking through a problem before giving you an answer.
This isn’t a bug. It’s a deliberate shift in how AI systems work, and it’s starting to change what they can actually do.
What Inference Time Compute Actually Means
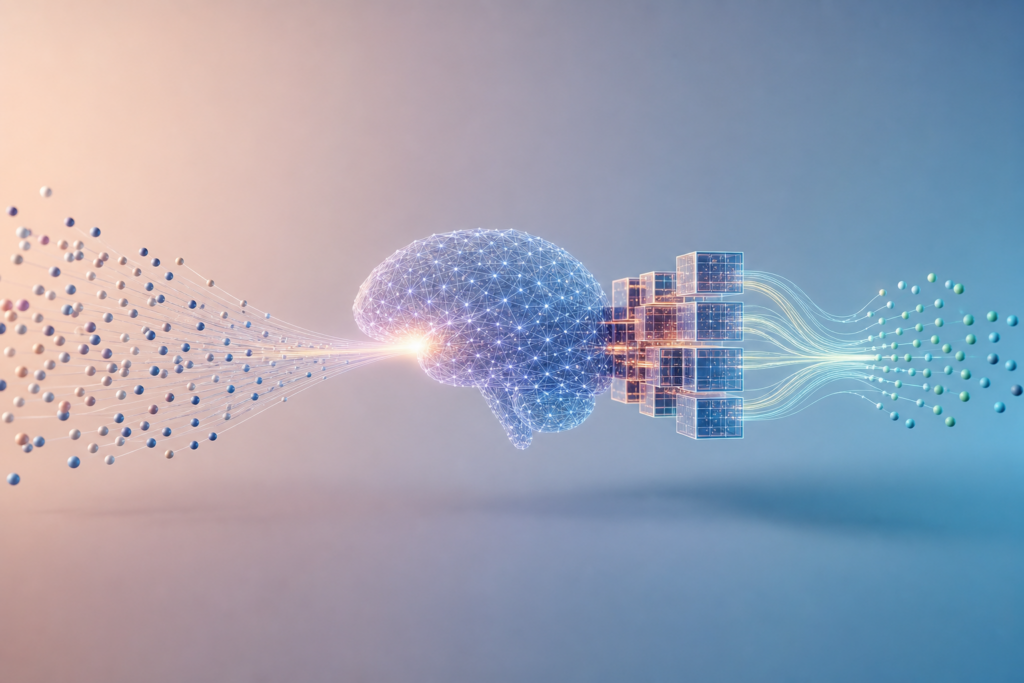
Most AI models process your prompt once and immediately start generating a response, token by token. That’s fast, but it doesn’t leave much room for reasoning or self-correction.
Inference time compute flips that model. Instead of rushing to answer, the AI uses extra processing cycles during the response phase to:
- Consider multiple approaches to a problem
- Check its own work for errors
- Explore different reasoning paths before committing to an answer
- Revise incomplete or contradictory logic mid-generation
Think of it like the difference between answering a tough question immediately versus taking a minute to think it through. The second approach costs more time and energy, but often produces better results.
Why Models Are Using It Now
For years, AI labs focused on making models bigger and training them on more data. That approach hit diminishing returns—massive models became expensive to train and run, without proportional improvements in capability.
Inference time compute offers a different path: instead of just scaling up training, you scale up thinking. OpenAI’s o1 model series, released in late 2024, was one of the first widely available examples. Claude and Gemini have since introduced similar features.
The trade-off is deliberate. These models cost more per query and take longer to respond, but they handle complex tasks—like multi-step math, code debugging, and logical reasoning—significantly better than standard models.
When It Actually Helps (And When It Doesn’t)
Inference time compute isn’t useful for everything. If you’re asking ChatGPT to summarize an email or rewrite a sentence, the extra thinking time won’t help much. The model already knows how to do that instantly.
Where it does help:
- Math and logic puzzles: Problems that require multiple steps and verification
- Code generation and debugging: Writing functions that need to handle edge cases or complex logic
- Planning and strategy: Tasks where the model needs to consider trade-offs or simulate outcomes
- Complex research questions: Queries that benefit from the model exploring multiple angles before answering
If you’re using a model with a “thinking” or “reasoning” mode (like Claude’s extended thinking or ChatGPT’s o1 models), you’re already using inference time compute. The model is running internal reasoning steps you don’t see before it delivers the final answer.
What This Means for You
If you’re choosing between AI models or pricing tiers, understanding inference time compute helps you pick the right tool. For everyday tasks—drafting emails, brainstorming ideas, quick summaries—standard models are faster and cheaper. For hard problems that need accuracy, models with extended reasoning are worth the extra cost and wait.
You’ll also start seeing this feature roll out more widely. Expect more models to offer “quick” and “deep” modes, where you can choose whether to prioritize speed or quality depending on the task.
This shift also hints at where AI development is headed. Instead of just building bigger models, labs are building smarter ones—systems that can allocate their resources dynamically based on how hard a problem is.
Want to stay sharp on AI developments like this? Subscribe to the One Two Three AI newsletter and get one useful AI idea in your inbox every day.